RAG evidence coverage: 66.25% → 91.25%, with 87% less time after tuning
Jev is a decision-only model that must pick from a fixed set of options. Applied first to request routing, it scored 81/98 against 77/98 for the existing JSON approach and 63/98 for GPT-5-nano on the same options, with a shorter decision time. I then applied it to RAG evidence selection, raising evidence coverage from 66.25% to 91.25%, and reduced its added latency by tuning candidates and parallel batches.
01 Background
Existing retrieval missed needed evidence and attached evidence even to unanswerable questions. The correct sources were all in the initial candidates, but for 76 of 90 questions they were cut when checking was limited to the first 8 pages. I needed a step that picks the right evidence and says when there is none.
Wrong evidence makes the whole answer untrustworthy, and users who lose trust stop coming back. Picking the right evidence turns document-based answers into a reason to keep using and paying for the service.
02 Experiments and improvements
Routing comparison and the decision to try RAG
Problem Some questions were misclassified as document edits, leading to the wrong action. Task types and additional conditions needed to be selected more accurately and quickly.
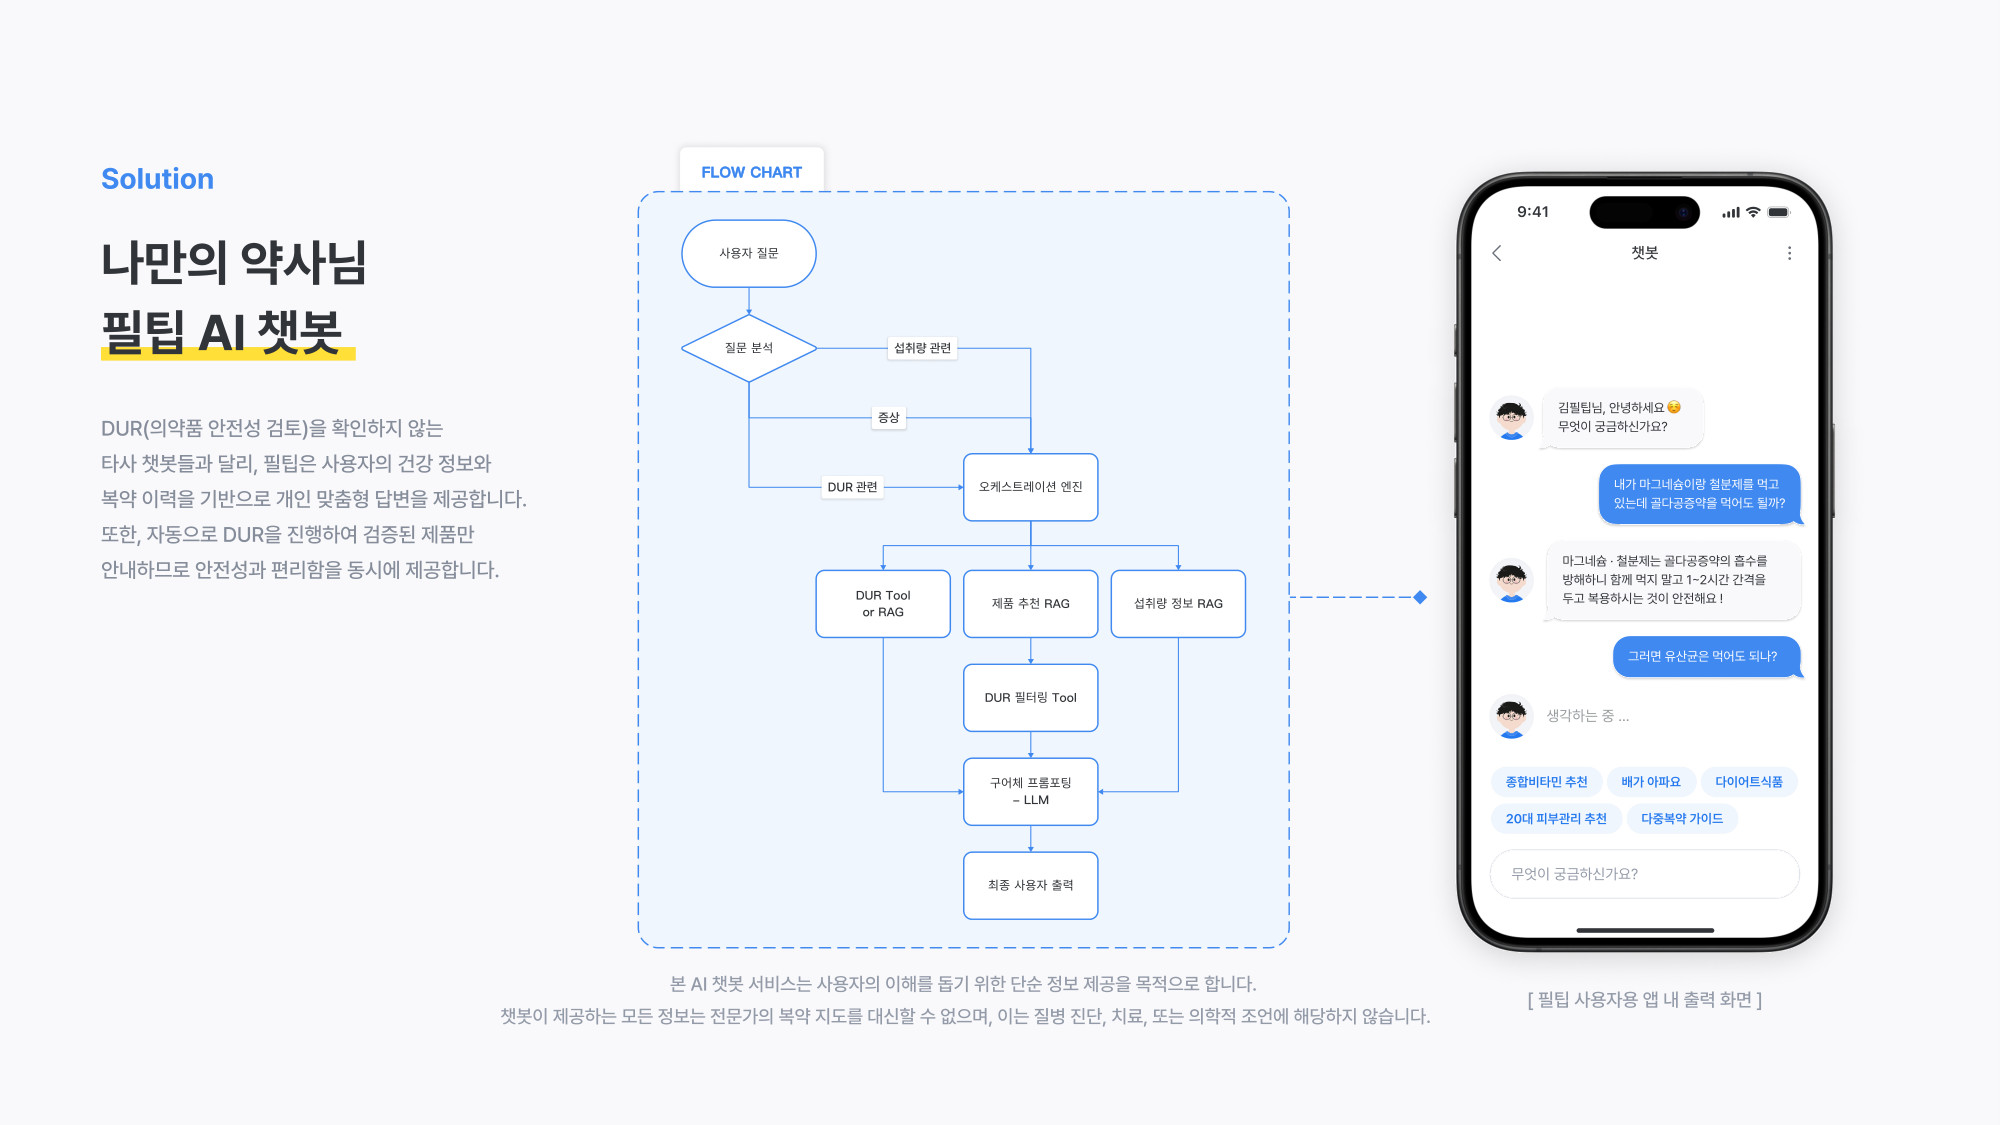
Experiment and result Applied Jev, a choice-based decision model released on September 14, to routing questions, document edits, document creation and folder organization. Across 98 requests, correct task types and additional conditions totaled 77 for the existing JSON approach, 63 for GPT-5-nano given the same options, and 81 for Jev. Median decision time improved from 8.967s to 0.658s. I measured API cost on the same 100 questions: about $0.0408 for Jev against about $0.1027 for the GPT approach given the same options.
Decision Jev showed promise on accuracy, speed and cost alike, so I decided to apply it to evidence selection, which the existing retrieval had not solved. I chose Jev for two reasons. First, having GPT pick the evidence cost about 2.5 times as much even with the same options and took longer, too heavy for a step that checks hundreds of candidates per question; re-ranking by tuning retrieval scores did not help either, as scores stayed similar across many hybrid weights and RRF settings. Second, embeddings sometimes failed to separate differences in Korean phrasing, so fitting one weight to questions from different fields would bring only small gains. Rather than polishing the ranking further, I had a model judge the needed evidence directly from the collected candidates.
Full-corpus inspection: evidence coverage on all 90 answerable questions
Problem Using the original question for retrieval and increasing semantic-score weight raised top-1 correct retrieval from 50 to 57 out of 110 questions. However, the experiment had some bias, and reliable evidence selection on new questions remained unsolved. Delivering reliable answers to general questions is the core of the project, so this quality had to improve.
Experiment and result Tested whether Jev could find evidence missed by retrieval. It inspected all 2,020 evidence units in a test Wiki without retrieval filtering and returned at most 8, matching the existing return limit. In a semantic evaluation allowing paraphrases, coverage on 90 answerable questions rose from 24/90 (26.7%) to 90/90 (100%). It returned no evidence for all 10 unanswerable questions. Median processing time was 1.511s for the original approach and 5.338s for Jev. Jev processed 26 batches of 80, with up to 4 in parallel. Full-corpus inspection took 2,600 calls for 100 questions, and the API reported roughly 124.5M input and 6.47M output tokens. I did not confirm the billed amount. To understand the size of the gap I traced where the existing retrieval dropped the answer. The page holding the reference sentence was in the initial candidate pool for all 90 questions, but 76 fell out at the step that limits inspection to the top 8 pages, 8 at the threshold of 85% of the best in-page score, and the remaining 2 at the final 8-evidence cap and the related-page lookup.
Decision The existing retrieval was discarding the answer before selection even began, so the gap cannot be read as a difference in selection ability over the same candidates. Full-corpus access found the evidence, but inspecting everything per question would grow calls as documents grew. Rather than set the deployment scope from this 90-question wiki alone, I decided to narrow candidates through retrieval first and let Jev pick the final evidence.
Controlled comparison on 500 candidates: 87.50% coverage
Problem Checking every piece of evidence was too costly to use in the service as-is. The evaluation questions were also concentrated in certain documents and included document titles. The original search judged from only some pages while Jev saw all evidence, so it was hard to tell whether the accuracy gap came from judgment or from access scope. I had to cut candidates and match the comparison conditions.
Experiment and result Created 100 new questions from 9 papers (80 answerable, 20 unanswerable) and fixed them before the runs. Both methods received the same 500 candidates with returns capped at 8, reference answers were excluded from inputs, and GPT and Gemini graded without seeing method names. Coverage rose from 66.25% to 87.50%, but sequential candidate processing raised median time from the original 0.431s to 9.090s.
Decision Jev selected better evidence under the same conditions, so I kept retrieval for candidate collection and Jev for final selection. Results on public papers and self-authored questions were not treated as general accuracy, and reducing the waiting added by sequential processing became the next task.
300 candidates and a parallelism comparison to reduce latency
Problem Answers start only after evidence selection finishes, so processing time is the user's waiting time. A 9.090s median for 500 candidates processed sequentially was far too long against the previous 0.431s to be usable. Still, the higher accuracy was worth keeping, so I set out to cut the time.
Experiment and result Since candidate count drives cost and speed, I cut candidates from the top 500 to 300 and ran up to 4 batches in parallel. Time fell to 2.251s, while questions with all required evidence increased from 70 to 73. The parallel count had been set without evidence, so I re-ran the same 100 questions with only parallelism changed to 4, 6, 8 and 10. Median selection time was 2.066, 1.165, 0.945 and 0.886s, and blind grading of the 42 questions whose selections differed gave 37, 38, 36 and 37 fully supported, with no real difference.
Decision Beyond 8 the gain was only 0.06s, and in production concurrent requests grow as workers × parallelism, so I chose 8. At 1.137s including candidate filtering it is still slower than the original 0.431s; I rejected cutting candidates further because some required evidence ranked below 250. I adopted Jev despite the added latency because accurate evidence is central to the service.
Comparing candidate generators to find the limits of the production setting
Problem Jev can only choose from what reaches it, so evidence missing from the candidate pool is unreachable. I needed to know how far the production candidate generator preserved the answer-bearing evidence.
Experiment and result Reusing stored scores, I regenerated rankings for four candidate generators and compared how well each preserved the 97 pre-registered citation groups across the 80 answerable questions: BGE-M3 alone, the production hybrid (0.75 embedding + 0.25 normalized BM25), RRF, and an alternating union. At 100 candidates, the questions that preserved every citation were 74/80 for BGE-M3 alone, 63/80 for the production hybrid, 63/80 for RRF and 65/80 for the alternating union. MRR@500 over each citation’s best rank was 0.1811 for BGE-M3 alone against 0.1245 for the production hybrid, with median ranks of 19 and 40. Beyond 300 candidates the four converged to 79/80 and 78/80.
Decision The production hybrid weighting ranks answer-bearing evidence lower than plain BGE-M3. At the current 300 candidates the gap is small, so I left production unchanged and recorded it as the first condition to fix before cutting candidates further.
03 Improved processing flow
flowchart TD
 Q[User question] --> S[Collect semantic and keyword search candidates]
 S --> C[Top 300 candidates]
 C --> J[Jev selects evidence in up to 8 parallel batches]
 J --> E{Sufficient evidence?}
 E -->|Yes| A[Pass selected evidence to answer generation]
 E -->|No| N[No evidence]
The evaluated evidence-selection design. Reference answers were used only for evaluation, never as retrieval or model inputs.
View Mermaid source
flowchart TD
 Q[User question] --> S[Collect semantic and keyword search candidates]
 S --> C[Top 300 candidates]
 C --> J[Jev selects evidence in up to 8 parallel batches]
 J --> E{Sufficient evidence?}
 E -->|Yes| A[Pass selected evidence to answer generation]
 E -->|No| N[No evidence]
04 Results and lessons
Questions with sufficient evidence: 53/80 → 73/80; total median time 1.137s
On a self-authored golden set of 80 answerable questions, the share with evidence supporting every required fact rose from 66.25% to 91.25%. On a separate 20 unanswerable questions, false evidence returns fell from 20 to 0. The improved selector was still slower than the original, but I chose Jev because accuracy mattered more to the service. I also tried grouping equivalent expressions: correct answers stayed similar on 76 questions (71 previously, 72 with Jev), while median decision time fell from 8.162s to 0.254s.
Retrieval stays a fixed pipeline of semantic, keyword and wiki-graph search, with the answer shown apart from its evidence and path. A query agent that plans its own retrieval was deferred until one question needs several plans and replanning; until then the fixed pipeline gathers the same evidence in fewer calls and is easier to trace. The speedup compares Jev before and after its own settings changed, and even after tuning it stays slower than the previous selector. Evidence selection has to finish before the answer, so the 1.137s remains user-visible waiting and shortening it is still open work. Retrieval gathers candidates and Jev makes the final evidence call, so the selection stage can be swapped on its own. The parallelism comparison ran once per condition, and only the 4-batch run was on a different day.